Imagine a leadership meeting. The team shows two commentaries on the same sales report and proposes giving more colleagues access to AI. The first commentary took a person 30 minutes of work. For the second, AI produced a draft in two minutes. The difference looks convincing on a slide. But the first figure measures human work; the second measures the wait for a draft.
An AI-generated draft is not yet something the business can act on. Someone still has to check the numbers, trace the sources, correct the conclusion, and answer questions from the person receiving the commentary. Count that work, too.
Before recommending further investment, I would want to see the whole process, from the request to an accepted, usable commentary. I would also want to know how people would use any time saved. A pilot can give you a reason to continue. It can also show, before you spend more, that further investment would not pay off. Either finding is useful.
What you need to know before investing more
I would start with three questions:
- Does the output meet our quality requirements?
- Do people save time, and can they use it?
- Can we manage the cost and risks of the new process?
If an answer is missing, name what you still need to test.
For this example, a commentary on a sales report must do more than read clearly. It needs the right reporting period and revenue definition, accurate figures, and a clear distinction between a documented reason for a change and a hypothesis. The person receiving the commentary needs to know whether they can rely on it when making a decision.
Write down the quality criteria before testing, then apply them to both methods. If people already disagree about what revenue includes, first clarify the meaning and reliability of the company’s numbers. Switching models will not resolve that disagreement.
Where the promised time savings went
The following numbers are made up to explain the calculation. They are not results from one of my projects or targets you should aim for. Assume the recipient accepts both commentaries at the same required quality.
The table counts active human work. The first row covers preparation and drafting in the current process, or preparing the prompt when using AI. We measure the two-minute generation run separately.
| Active human work per commentary | Current process | With AI |
|---|---|---|
| Preparing a draft / preparing the AI prompt | 20 minutes | 5 minutes |
| Review and corrections | 8 minutes | 15 minutes |
| Handoff of the result | 2 minutes | 2 minutes |
| Total | 30 minutes | 22 minutes |
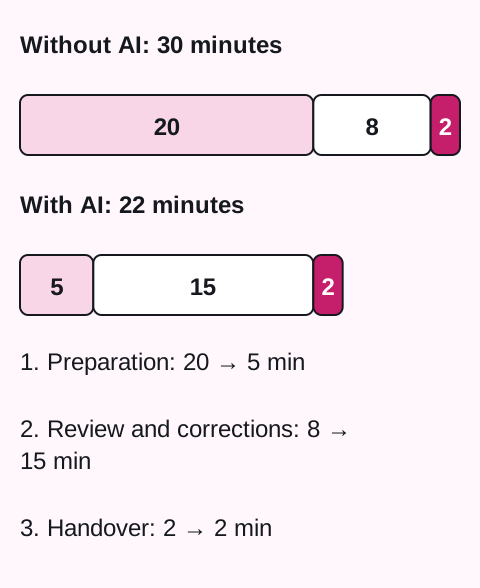
In this example, AI speeds up the first draft, but review takes longer. The difference in human work is eight minutes per commentary. The two minutes of unattended generation are not in the table: the person can do something else while the model runs. If someone has to watch the process, include that time in their work.
At 100 comparable commentaries per month, the gross difference would be 13 hours and 20 minutes. Add another model assumption: the new process requires two hours of additional recurring maintenance per month. That leaves 11 hours and 20 minutes of capacity for other work. The estimate still excludes the tool’s price, one-time setup, and any further investment needed to expand its use.
To understand when the recipient gets the result, also measure elapsed time from the initial request to acceptance. That includes waiting. When activities overlap, you cannot calculate it simply by adding the entries in the table.
Saved time needs a useful destination
The total hours saved will not tell you whether to expand the pilot. It matters whose time is freed up, which tasks it comes from, and what that person can do instead.
In my own work, the main gains are finishing projects sooner and getting more done. That does not automatically mean more free time with my family. I often fill the time with another project because I am fascinated by what has become possible. Sometimes I work longer than I would like. Faster completion and more free time are two different outcomes for me.
Documentation is one place where I see better quality. I used to let it slip behind the rest of the work. Now an agent can record what we are building and why as we go. That gives me a knowledge base for a future product handoff. Having the notes does not yet establish that someone else can continue from them; I would need to test that during the handoff.
If a salesperson can use the time to prepare proposals that are currently being postponed, the business has a reason to keep testing that benefit. If the saving is spread across many people in a few minutes here and there, with little practical change in their work, the same value will be harder to demonstrate. A time sheet alone cannot tell you which situation you have.
Look at how the work moves between people, too. If a junior employee prepares the draft and your busiest analyst takes on the corrections, the total minutes can fall while your capacity bottleneck gets worse. Ask the team to show who saves time and who takes on more work.
Saved hours do not automatically reduce payroll spending. To assess the financial benefit, you need the operating cost, the time required from each role, and the value of the additional work those people could do.
Count one-time setup separately from recurring costs. Compare costs and benefits over the same period. Record the work already invested in the pilot, too. But judge the next budget by what it can deliver from this point forward.
What the team should provide for a credible comparison
Leadership does not need to take over technical testing. It does need to understand what the results cover. I would ask the person leading the pilot for five things:
- What you are testing and who accepts the output. Write down the quality requirements. Identify which errors can be corrected and which require a stop. Agree on the data the tool may read and the actions it may take.
- How the test reflects everyday work. Include easy and difficult tasks, incomplete inputs, and common exceptions. Remember that someone solving the same task a second time already knows the answer. Alternate the order of the methods or use tasks of comparable difficulty.
- How much work people did. Count preparation, tool operation, review, corrections, and handoff. Include errors found by the recipient. If someone does the task manually after three failed AI attempts, count the whole sequence. Record the role for each activity; measure delivery time separately.
- How the process performed after tuning ended. Keep some tasks for a final test. Results can look overly favorable on the cases used to refine the instructions. Record the model, instruction, and source versions. If they changed during the comparison, distinguish results before and after the change.
- How much the results vary. Show the number of cases, how many were accepted without corrections, average and median time, and the most demanding corrections. Assess routine tasks separately from exceptions. The number of cases you need depends on the variety of the work and the consequences of an error. A small test cannot establish reliability across the whole operation.
If the same input produces different outputs, repeat some of the difficult cases. Do not count those attempts as new, independent business situations. A decision requires a clear account of what was tested, not just a larger number on a slide.
Expand, revise, or stop
When I decide a task is worth automating, I usually look for another approach after an unsuccessful attempt. One failed method does not mean the original problem is no longer worth solving. But another attempt needs to test something new. If I keep repeating the same approach without a benefit, persistence alone does not justify continuing.
Write down the conditions for continuing in advance. The required savings, acceptable amount of rework, and risk limits will differ between an internal working draft and a document sent to a customer. A universal percentage would conceal those differences.
Expand when the pilot meets the agreed conditions, recipients can use the output, and the benefit justifies the additional cost. Approve a defined next scope, an owner, the necessary resources, and a date for another review. Results from one process do not justify deploying it everywhere.
Revise and test again when you understand the cause of a problem and can define a further test. In our example, a missing link to the source of a number might be making review slower. You could test whether adding that source reduces review time while maintaining quality. The next attempt needs a clear question, a limited budget, and an agreed stopping condition.
Stop when corrections consume the benefit, nobody uses the result, or an unacceptable error occurs. The pilot has supplied evidence for a decision before a larger investment. Expansion does not have to be its outcome.
What a recommendation to leadership could look like
Our illustrative calculation does not yet support a broad rollout. We have an estimate of available capacity, but not all the costs or results from a representative set of tasks. An honest decision brief might read:
Decision: Whether to expand the use of AI for preparing sales report commentaries.
What the example suggests: At the same quality level, human work would fall from 30 to 22 minutes. At 100 commentaries and two additional hours of monthly maintenance, that would free up 11 hours and 20 minutes.
What is missing: Validation on routine and difficult tasks, the distribution of work by role, the cost of the next step, and an agreement on how the saved time would be used.
Proposed next step: Do not expand yet. Define a test to obtain the missing evidence, with an owner, scope, budget, and decision date agreed in advance.
You can use the team worksheet for your own pilot. It includes a decision-brief template and a record for each test case. Filling it in also makes the remaining unknowns visible.
This approach fits bounded tasks whose output can be checked. Time measurements alone are insufficient for rare, serious errors or effects that only become visible months later. And if AI enables work the business has never done before, assess the value of that new output; comparing it with a nonexistent previous process would not be meaningful.
If leadership and the team disagree about what the pilot demonstrated, we can review the process, criteria, and evidence together. That is the basis of my AI workflow sprint. Tell me what work you are testing and what you need to decide.
Methodological background: Anthropic discusses evaluating AI agents, including success criteria, variation between runs, and checking actual outcomes. The capacity calculation and leadership brief in this article are a proposed approach, not an adopted standard or a measured case study.