Imagine a business that compares confirmed orders for the last two complete weeks every Monday. Management wants to know whether orders are rising or falling and whether anything needs attention. An analyst prepares the figures and a short commentary. AI can help, but how much it can do depends on the information it has and the work it is allowed to take on.
We will follow this hypothetical example through six levels, adding saved instructions, data access, business context, updates to working rules, and independent execution. At each level, we will look at what changes for the analyst. Then I will show how I combine these capabilities in my own work on HeyRup.
This is my practical map, not a validated scale of ability. The capabilities can overlap, and you do not need to work through every level. Chat may be enough for a one-off piece of writing. A recurring report may justify a more deliberate approach to data sources and changes in business rules.
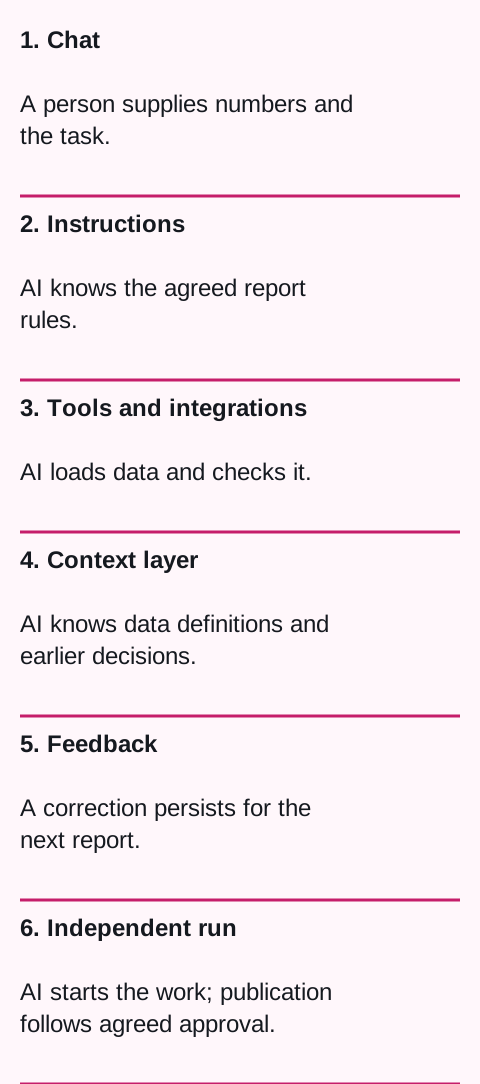
1. Chat: you supply the material for each task
The analyst pastes a table into a chat and asks AI to compare the two weeks and draft a commentary. They get an initial response, ask follow-up questions, or clarify the request. Chat is useful for a task with these clear boundaries: it can help examine the material and turn it into a readable explanation.
The table still needs to contain the information required to answer the question. If it only contains two totals, AI can describe the difference. Those figures alone cannot tell it whether the analyst correctly excluded canceled orders. Nor does a decline explain whether demand weakened, a sales channel failed, or something else happened.
The analyst therefore supplies both the figures and an explanation of what they mean. They also check that the commentary distinguishes an observed change from a possible explanation. For the next report, they need to make sure AI has the necessary information again.
2. A workspace: you save the recurring instructions
After a few Mondays, it becomes clear that much of the request stays the same. The analyst saves instructions in a workspace or project: compare complete weeks, show the change as a count and a percentage, and do not explain its cause without supporting evidence. They add an example of a good commentary and the rule that canceled orders must be excluded.
Next time, they supply a new table and ask for the next report. They no longer have to explain the format or basic rules. They still provide current data and check that the saved instructions match what the business needs.
This makes the work easier to repeat. But the analyst still has to transfer the table. If that is an unnecessary manual step, connecting AI to the data source may be a useful next move.
3. Tools and integrations: AI can retrieve the material
The analyst gives AI access to an approved source containing individual orders. Instead of downloading and pasting a table, they can ask it to prepare last week's commentary. AI uses a connected tool to retrieve the data and follows the saved instructions. In this article, I use the term agent for a model that can choose and carry out steps using tools.
Access should match the task. Preparing a report may only require permission to read an approved export. The agent does not need permission to change orders or send messages to management. These boundaries should be set when the tools are connected.
A working connection does not explain what the data means. An agent might be able to read an order-status column without knowing which statuses to include. To apply the business definition, it needs somewhere to find that definition and a clear link between the rule and the data.
4. A context layer: you connect data to its meaning
The saved instruction to “count confirmed orders” was a useful start. It is too brief for working directly with business data, though. We need to specify the source, the order statuses to include, which date assigns an order to a week, and the cutoff for deciding whether it has been canceled.
In our example, orders belong to a week based on their confirmation date. At the Monday reporting cutoff, we exclude those already canceled. The definition must also name the specific fields and statuses used in the calculation.
The agent gets a way to find this definition and the corresponding data. It also knows who can resolve ambiguity. Several tasks can then use the same definition. If instructions conflict, an agreed source takes priority.
I call this organized material a context layer. It can span documentation, databases, and other tools. What matters is that the agent can retrieve the relevant context for the task. The report can then identify its data source, reporting period, and definition, giving the analyst a basis for checking how the result was produced.
Documentation alone does not guarantee a correct calculation. Someone still needs to verify that the query or procedure actually implements the definition. I explore how to organize this material in my article on a second brain for AI. Here, the next question is how to keep that context from going out of date.
5. A nervous system: a correction improves the next run
Suppose the analyst checks the underlying data and finds that the calculation included a canceled order. The agent traces the problem to a missing filter in the data query. If it only rewrites the commentary, it could make the same mistake next Monday.
The fix therefore needs to reach the query itself. Within its permissions, the agent fixes the query or prepares a change for approval. It adds a check to catch the same kind of mistake and records what changed and why. The business definition stays the same; the calculation is being brought into line with it.
A change to the business definition is a different situation. The approved decision and its effective date need to be recorded, and the reporting procedure updated. The next report must use the new version and flag any loss of comparability with earlier figures.
“Nervous system” is my metaphor for this connection between work and feedback. An important finding reaches the source that the next task will use. Accumulating notes is not enough: the system needs to distinguish a proposal from an approved decision and establish who may make changes. Agents can handle the recording and follow-up work under agreed rules.
6. Governed autonomy: you delegate a bounded process
Until now, the analyst has started the work each time. An agent could instead retrieve the data, calculate the figures, run checks, and draft the report every Monday on its own. A schedule alone only automates the start. The degree of autonomy also depends on which subsequent actions the agent can choose and complete without a person.
In our example, it gets specific checks: the source must cover both complete weeks, canceled orders must be excluded, and totals must reconcile with the underlying data. If a check fails, the process must stop short of a finished report. The agent passes the problem and the supporting material to the analyst.
If the checks pass, it produces a draft with links to its sources. In this setup, the analyst still reviews the commentary and decides whether to send it to management. In particular, they check the evidence behind any explanation of the change. Correct totals do not establish why orders fell.
The boundaries can differ for each task. What matters is how the result can be verified and what an error would cost. Preparing an internal draft has different consequences from changing prices or messaging a customer. Permissions and human review need to reflect that difference.
On HeyRup, the agent does the work and I assess the result
I have built HeyRup with AI as a normal part of development from the start. I have not written code or database queries myself in a long time. The agent handles implementation. My main contributions are defining the requirements, making product decisions, and checking what a person can actually accomplish with the app.
The agent and I develop the product requirements together. It implements and tests the solution. I then click through the app as a user and report bugs or shortcomings for it to address. Often, I find something we did not work out fully in the requirements: the user flow is too complicated, the screen has too many elements, or the next action is unclear. The agent revises the solution based on that feedback.
This is where I distinguish a technically working app from one that solves the user's task well. I do not review lines of code myself. I consider the agent more capable than I am at coding and many other technical tasks. I still need to judge whether we defined the right thing to build and whether the result makes sense to the person using it.
The agent also handles website and app deployments for me. When I was dealing with problems with Google, it communicated with support on my behalf. My involvement therefore depends on more than how many steps the agent completes. It also depends on which outputs I want to see and which decisions I keep.
To build on previous work, the agent needs current source material. My personal HQ holds a map of projects and working rules; each project HQ holds its specific decisions and context. Under my instructions, agents record findings in Notion and lasting changes in the relevant repository. The next task can pick up from there without my having to explain the whole project again.
Quality checks belong in the task
I use the same approach for articles. I have quality categories, instructions for checking each one, and minimum scores. Subagents review the individual categories. If a part falls short, it needs revision. Producing a long piece of writing or making it look finished is not enough.
The assessment needs evidence in the output. A factual claim needs a source, instructions need the steps required to follow them, and an article needs to deliver on its headline. A score alone does not guarantee correctness. It helps me identify what needs fixing and how to assess the revision. For my personal articles, I also want to see the final version before publication.
The aim is to avoid finding the same shortcomings in every draft myself. When the agent catches and fixes them against criteria set in advance, my review can focus on decisions or input that need to come from me. I am trying to reduce the number of revision rounds that require my involvement.
When I increased autonomy, and when I limit it
One automated workflow showed me why a scheduled start is not enough. A later step was waiting for input from me or a preceding agent. I had not provided the material the earlier step needed, and the chain stopped. If I wanted the workflow to function while I was away, I needed to change how the work was handed off.
In that case, I gave the agent more independence and tightened the output checks at the same time. My ongoing input had previously supplied some of the oversight. For more independent work, I needed to define an acceptable output and what to check when I was not there. Adding another timer cannot resolve a dependency on missing human input.
I limit autonomy when results are poor or I discover that the existing checks missed something significant. A critical error is a reason to review the boundaries. I also scrutinize client deliverables more closely because I need to stand behind them. I decide how much work to delegate independently based on actual experience and the consequences of an error.
I would start with an ambitious task and close oversight
I would not give a beginner a list of system components they should avoid building. I would be comfortable asking an agent for the whole result, while checking its work closely at first. As repeated use shows that it can handle my process without basic mistakes, I can give it more freedom and keep refining the rules.
Someone who has only chatted with AI and has no experience connecting tools needs to think through their first integration and its consequences. For our report, they can start with one table and verify the figures. They can add access to the source once they know what the agent needs to retrieve and how to check the result. An ambitious task can go alongside gradually expanding access.
That is the purpose of this map for me: identify what the agent needs to produce a useful result and how I will know it has delivered. You do not need to build my entire HQ first. Start with work you understand, then improve the system through experience completing it.
How to find your own next step
Start with one recurring task where you know what a good result looks like. It might be a report, meeting preparation, or sorting emails. Describe what you do, what AI does, and where the work gets stuck. That gives you a place to look for an improvement.
The prompt below helps you examine that process. Its findings will depend on the information you supply; the model cannot independently establish how you work. A description and an example without sensitive data are enough to start. Before sharing documents, check that the tool is allowed to process them.
Help me map how I currently use AI in this specific workflow: [describe the work].

Use only information in this conversation or in materials I explicitly attached. Do not pretend you can access my memory, files, or systems you cannot see. Separate what is supported, what you infer, and what you do not know. If important information is missing, ask me no more than 8 specific questions.

Use the six levels from the article as a working map, not a certified standard:
1. Chat: one-off task; I provide the context manually.
2. Repeatable workspace: saved instructions, templates, or a separate environment for similar tasks.
3. Tools and integrations: AI works with approved files, apps, or data.
4. Context layer: AI can find current definitions, sources of truth, decisions, and rules.
5. Live nervous system: changes, decisions, and corrections flow back into the right context for future work.
6. Governed autonomy: recurring steps run on their own within clear limits, with checks and human intervention where needed.

Assess these areas separately:
- everyday tasks and how often they repeat
- workflows and tools
- context quality and availability
- how information is updated and decisions are handed off
- output checks and the cost of an error
- autonomy and human oversight

For each area, give concrete evidence, a level or range, and the information you still do not have. Do not give me one overall score or assume a higher level is always better. Finish by recommending one practical change to this workflow. Explain how I can recognize an improvement on the next task, verify the result, and decide what should remain under human control.
Choose one change and try it on the next task
If the discussion reveals that you keep rewriting the same request, save the instructions and note what you still need to add next time. If moving tables takes most of the effort, try limited access to the source. If conflicting definitions produce inconsistent results, agree on the rule first and decide where it should be retrieved from.
For the Monday report, progress can be quite concrete: fewer manual steps, figures that match the source, and commentary that does not present a guess as an explanation. Once that process works, consider giving the agent more independence. Also check what it does when data is missing or a check fails.
A finished-looking output can make it tempting to skip verification. In its AI Fluency Index, Anthropic observed less explicit fact-checking and identification of missing context in conversations that produced artifacts. The study could not see checks outside the chat and does not establish what caused the difference. I take it as a reminder to make verification part of the task.
For me, moving toward a “nervous system” means that each task can use what earlier work established. Sometimes saved instructions are enough; elsewhere, connected tools and automations are worth adding. Start where you currently repeat unnecessary work or lose important context.
Further reading: Every: The Eight Levels of AI Adoption, Anthropic: AI Fluency Index, and Simon Willison: Context engineering. These offer different perspectives on working with AI. The six levels in this article are my own synthesis.